MOSS-Image JSON Layout Tutorial: bbox, yxyx and Coordinates
Write MOSS-Image layout prompts by hand: the summary and items fields, yxyx bounding boxes in centered pixel coordinates, a converter, and examples to copy.
This is an unofficial guide. MossImage Studio is a community site and is not affiliated with OpenMOSS. The format below comes from the official MOSS-Image repository, the user guide and the prompt enhancer skill, checked on October 25, 2026.
Besides plain text, MOSS-Image can take a JSON layout as its prompt: one description of the whole scene, then a list of elements, each with its own bounding box. It is how you put a title, a product or a block of text exactly where you want it. OpenMOSS labels the feature experimental, but it is built into both official checkpoints, MOSS-Image-Base and MOSS-Image-SFT.
This tutorial covers the format, how the coordinates work, and how to convert boxes from a design tool.
The official example
This is the example from the README, for a 1024×1024 canvas:
{
  "summary": {
    "meta": ["poster"],
    "canvas": "single",
    "caption": "A minimalist travel poster with a cream background, a blue mountain illustration, and the title EXPLORE at the top."
  },
  "items": [
    {
      "label": "text",
      "caption": "Large dark-blue uppercase title centered at the top.",
      "text": "EXPLORE",
      "bbox": [-416, -384, -288, 384]
    },
    {
      "label": "object",
      "caption": "A flat blue mountain illustration in the lower center.",
      "bbox": [-192, -288, 384, 288]
    }
  ],
  "bbox_coord_space": "abs_centralized",
  "bbox_format": "yxyx"
}
Field by field
| Field | What it holds |
|---|---|
summary.caption | The overall scene and style: background, medium, palette, mood. |
summary.meta | ["poster"] in the official example. The docs do not list other values. |
summary.canvas | "single" in the official example. Not documented further. |
items | One entry per element, in a flat list. |
items[].label | The element type. The official example uses "text" and "object". |
items[].caption | What the element looks like: font, color, size, material. |
items[].text | For text elements, the exact words to render. |
items[].bbox | The element's box as [y_min, x_min, y_max, x_max]. |
bbox_format | "yxyx": y comes first in every box. |
bbox_coord_space | "abs_centralized": pixel coordinates measured from the center of the canvas. |
Since the docs only show meta: ["poster"] and canvas: "single", keep those values unless you have a reason to change them.
How the coordinates work
abs_centralized means:
- Absolute pixels. Coordinates are real pixel positions on the output image, not fractions.
- The origin is the center of the canvas. On a 1024×1024 canvas, both axes run from −512 to +512.
- x grows to the right, y grows downward. So negative y is the top half of the image.
For a canvas of width W and height H, take an ordinary top-left pixel coordinate and subtract half the canvas:
x_centered = x - W / 2
y_centered = y - H / 2
And because bbox_format is "yxyx", every box is written [y_min, x_min, y_max, x_max]. Many tools use [x_min, y_min, x_max, y_max], so this is the easiest thing to get wrong.
OpenMOSS chose absolute pixels on purpose: the user guide says they believe absolute coordinates suit layout control across resolutions and aspect ratios better than relative ones. The flip side is that a layout belongs to one canvas size. Generate at the same width and height you laid it out for.
Decoding the official example
Convert the two boxes back to top-left coordinates by adding 512:
- Title
[-416, -384, -288, 384]: y from 96 to 224, x from 128 to 896. A band 768 pixels wide and 128 tall, centered near the top. - Mountain
[-192, -288, 384, 288]: y from 320 to 896, x from 224 to 800. A 576×576 square in the lower center.
That matches the captions: the title sits at the top, the mountain in the lower center.
Converting boxes from a design tool
Design tools give you a box as left, top, width and height, measured from the top-left corner. This function converts one to a MOSS-Image box. It rounds outward so a box never shrinks, which matches what OpenMOSS's prompt enhancer does with fractional edges:
import math

def to_moss_bbox(left, top, box_w, box_h, canvas_w, canvas_h):
    """Top-left pixel box -> MOSS-Image [y_min, x_min, y_max, x_max] from the center."""
    cx, cy = canvas_w // 2, canvas_h // 2
    return [
        math.floor(top) - cy,
        math.floor(left) - cx,
        math.ceil(top + box_h) - cy,
        math.ceil(left + box_w) - cx,
    ]

# The EXPLORE title: a 768 x 128 box at (128, 96) on a 1024 x 1024 canvas
print(to_moss_bbox(128, 96, 768, 128, 1024, 1024))  # [-416, -384, -288, 384]
The same in JavaScript:
function toMossBbox(left, top, boxW, boxH, canvasW, canvasH) {
  const cx = canvasW / 2;
  const cy = canvasH / 2;
  return [
    Math.floor(top) - cy,
    Math.floor(left) - cx,
    Math.ceil(top + boxH) - cy,
    Math.ceil(left + boxW) - cx,
  ];
}
MOSS-Image canvas sizes are multiples of 16, so half the width and height are always whole numbers.
OpenMOSS's prompt enhancer skill works the same way: you draft boxes as [x_min, y_min, x_max, y_max] from the top-left, with the canvas width and height, and its compile_prompt.py script writes the compact abs_centralized / yxyx JSON. It rejects boxes that fall outside the canvas instead of silently clipping them.
A landscape example
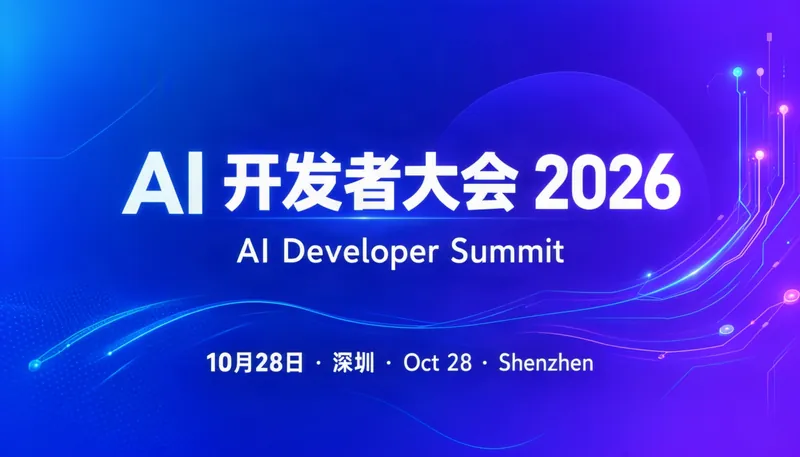
Here is a layout we wrote for a 1344×768 banner, the 16:9 size our generator uses. The x axis runs from −672 to +672 and the y axis from −384 to +384:
{
  "summary": {
    "meta": ["poster"],
    "canvas": "single",
    "caption": "A wide tech conference banner with a clean blue and violet gradient background and thin abstract circuit lines."
  },
  "items": [
    {
      "label": "text",
      "caption": "Large bold white title, centered in the upper half.",
      "text": "AI 开发者大会 2026",
      "bbox": [-224, -480, -64, 480]
    },
    {
      "label": "text",
      "caption": "Smaller light-gray English subtitle below the title.",
      "text": "AI Developer Summit",
      "bbox": [-32, -320, 48, 320]
    },
    {
      "label": "text",
      "caption": "A thin row of small white text along the bottom edge.",
      "text": "10月28日 · 深圳 · Oct 28 · Shenzhen",
      "bbox": [240, -400, 304, 400]
    }
  ],
  "bbox_coord_space": "abs_centralized",
  "bbox_format": "yxyx"
}
In top-left pixels, the title box spans x 192 to 1152 and y 160 to 320, the subtitle sits just below it, and the footer row runs along y 624 to 688. Move the boxes around to taste.
Using a layout
- Python: serialize the layout with
json.dumps(layout, ensure_ascii=False)and pass the string as the prompt, with the samewidthandheightthe coordinates were written for.ensure_ascii=Falsekeeps Chinese text readable instead of escaping it. - Gradio (the official demo app): paste the JSON into the Prompt field and set the matching width and height.
- ComfyUI: the layout-guided templates build the layout for you. You draw boxes in
Create Bounding Boxes, caption each one, and theMOSS-Image Layout Promptnode turns them into the prompt. See our MOSS-Image ComfyUI workflow guide.
import json

prompt = json.dumps(layout, ensure_ascii=False)
image = pipe(
    prompt,
    width=1024,
    height=1024,
    num_inference_steps=50,
    guidance_scale=3.0,
    uncond_skip_layers=[22],
).images[0]
pipe here is the Diffusers pipeline from the model card; our Base vs SFT guide shows how to load it.
On mossimage.studio
Our MOSS Image AI generator works in text mode for now; a layout editor is coming. Text prompts already go through prompt expansion, which plans a structured layout from your description before generating and keeps the text you asked for. Describing positions clearly in words gets you a long way. Here is the EXPLORE poster as a text prompt:
Prompt
A minimalist travel poster with a cream background. The large dark-blue uppercase title "EXPLORE" is centered at the top, and a flat blue mountain illustration fills the lower center.
Try this promptTips for good layouts
These follow the guidance in OpenMOSS's prompt enhancer skill:
- Box coherent units. One box for a title, one for a product, one for a paragraph. Split only when parts need to be placed independently.
- A box marks a position, not a frame. It does not draw a border, panel or sticker. If you want one, describe it in a caption.
- Overlap is fine. Natural occlusion, such as a title over a photo, is allowed.
- Exact words go in
text, appearance goes incaption. Keep the visible string verbatim intext, including punctuation and line breaks, and describe its font, color and size in the caption. - Global style goes in
summary.caption. Palette, lighting and medium belong to the whole image. - Keep captions and boxes consistent. A caption that says "at the top" should have a box at the top.
- Keep instructions out of captions. Captions describe what is visible. Notes about the JSON or the conversion belong somewhere else.
Common mistakes
- Writing
xyxyboxes. MOSS-Image expects[y_min, x_min, y_max, x_max]. - Forgetting to subtract the center. Top-left pixel coordinates put every box in the wrong place.
- Changing the canvas size. A layout written for 1024×1024 will not line up at 1344×768.
- Using normalized coordinates. Coordinates on a 0 to 1 or 0 to 1000 scale are not the format MOSS-Image layouts use.
- Boxes outside the canvas. Every coordinate must stay within half the width and half the height of the canvas.
Sources
- OpenMOSS/MOSS-Image on GitHub, layout-to-image section
- MOSS-Image user guide, layout prompts
- MOSS-Image prompt enhancer skill
- MOSS-Image in ComfyUI, ComfyUI documentation
More Posts
MOSS-Image Prompt Guide: Chinese and English Text in Images
Write MOSS-Image prompts that render clean Chinese and English text: describe the finished image, quote the exact words and control line breaks. With examples to try.
MOSS-Image ComfyUI Workflow: Models, Templates and Settings
Run MOSS-Image in ComfyUI: the four official templates, which model files to download and where they go, and the steps, CFG and SLG settings that matter.
MOSS-Image Base vs SFT: Which Checkpoint Should You Use?
MOSS-Image ships as two checkpoints, Base and SFT. What SFT changes, which one to pick for making images or training LoRAs, and how to run each in ComfyUI or Python.